AI-101 Day 41: Evals & benchmarks, can you trust the score?
Every model launch opens with the same bar chart. Here is why that number needs reading, not believing.
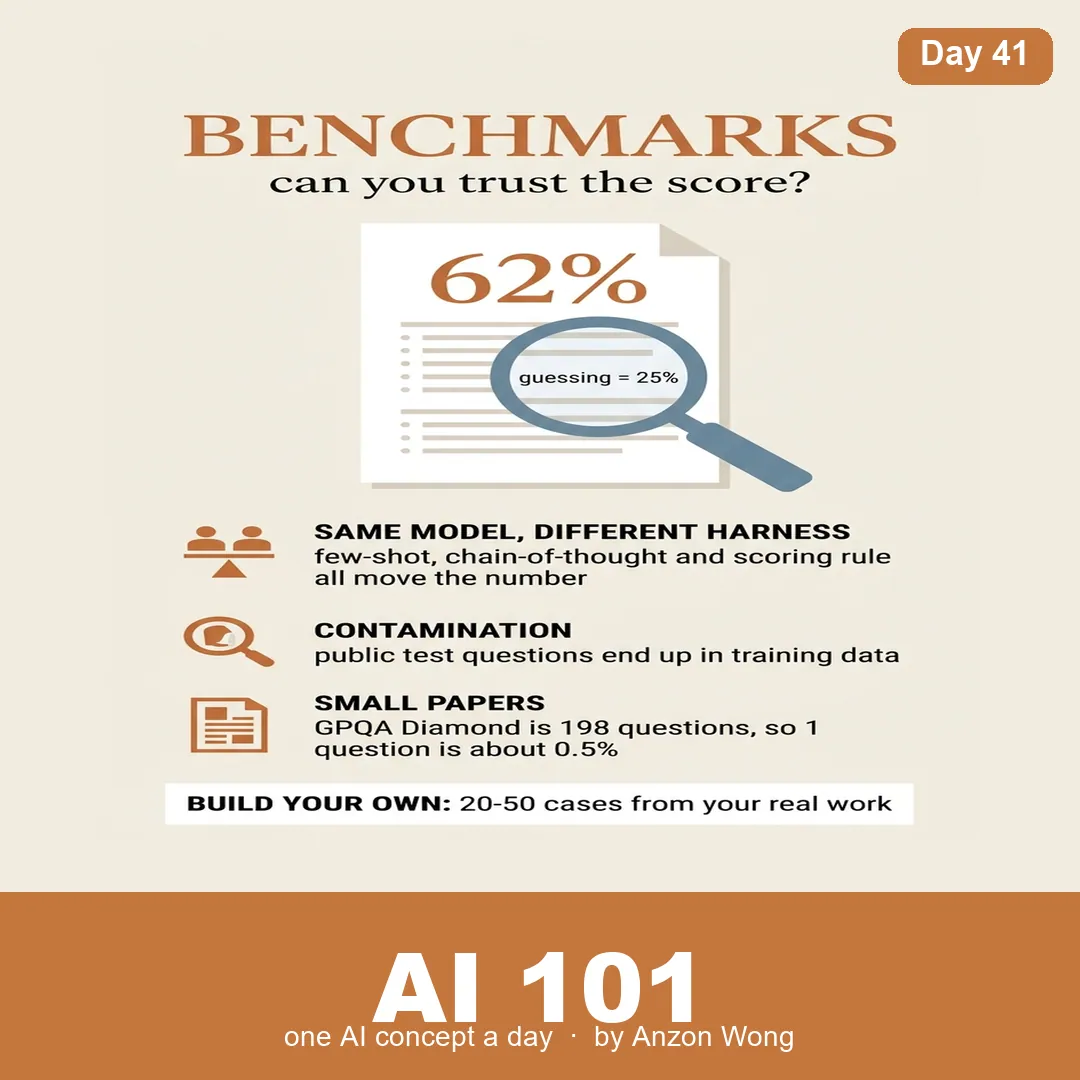
📏 What a benchmark is: a fixed set of questions plus an automatic scoring rule. MMLU is 15,908 multiple-choice questions across 57 subjects, four options each, so random guessing scores 25%. The floor isn't zero.
🔧 The same model can score differently on the same test. Few-shot or zero-shot, chain-of-thought allowed or not, and whether you compare option log-likelihoods or actually generate and parse an answer, each of those moves the number by points. Two labs reporting different scores for one model usually aren't lying; they ran different harnesses. A score without its setup is a number without units.
🦠 Contamination. Benchmark questions are public on the internet. Training data is scraped from the internet. If the answers are already in the training set, the score measures memory, not reasoning, which is why n-gram overlap checks and canary strings exist, and why GPQA was deliberately written to be Google-proof. MMLU itself was later audited and found to contain mislabelled answers, so even a clean run isn't scored against a perfect key.
Two labs reporting different scores for one model usually aren't lying; they ran different harnesses.
🔬 The tests are smaller than you think. GPQA Diamond is 198 questions. One question is worth about half a percentage point, so "1.5 points ahead" means three more questions right. On a bar chart that reads as a generation leap. And watch for pass@k or maj@32: answering 32 times and taking the majority is not the same skill as answering once.
🧭 Benchmarks aren't useless, they're the only shared ruler the industry has. But they measure performance on that paper, not on your job. SWE-bench measures fixing real GitHub issues in Python repos. Useful. Not the same question as "can it do my work".
Three things worth keeping:
• 📐 Ask how it was scored before you read the score, shots, CoT, sample size, and who chose the benchmark
• 🧪 Build your own, 20 to 50 cases from your actual work, an explicit definition of pass, re-run on every model. It's the only score that's about you
• 📉 When a benchmark saturates, the test changes, not the models, that's why GPQA, SWE-bench and ARC-AGI exist
📌 Takeaway: a benchmark is an exam paper, not a guarantee. The score that predicts your outcome is the twenty cases you wrote yourself.
More in Teaching
All → AI-101 Day 42: Diffusion, why image models work nothing like text models
 AI-101 Day 40: The agentic loop, think, act, observe, repeat
 AI-101 Day 43: Computer-use agents, the model watches your screen and moves the mouse
 AI-101 Day 44: Function calling and structured output, making a model emit something a…